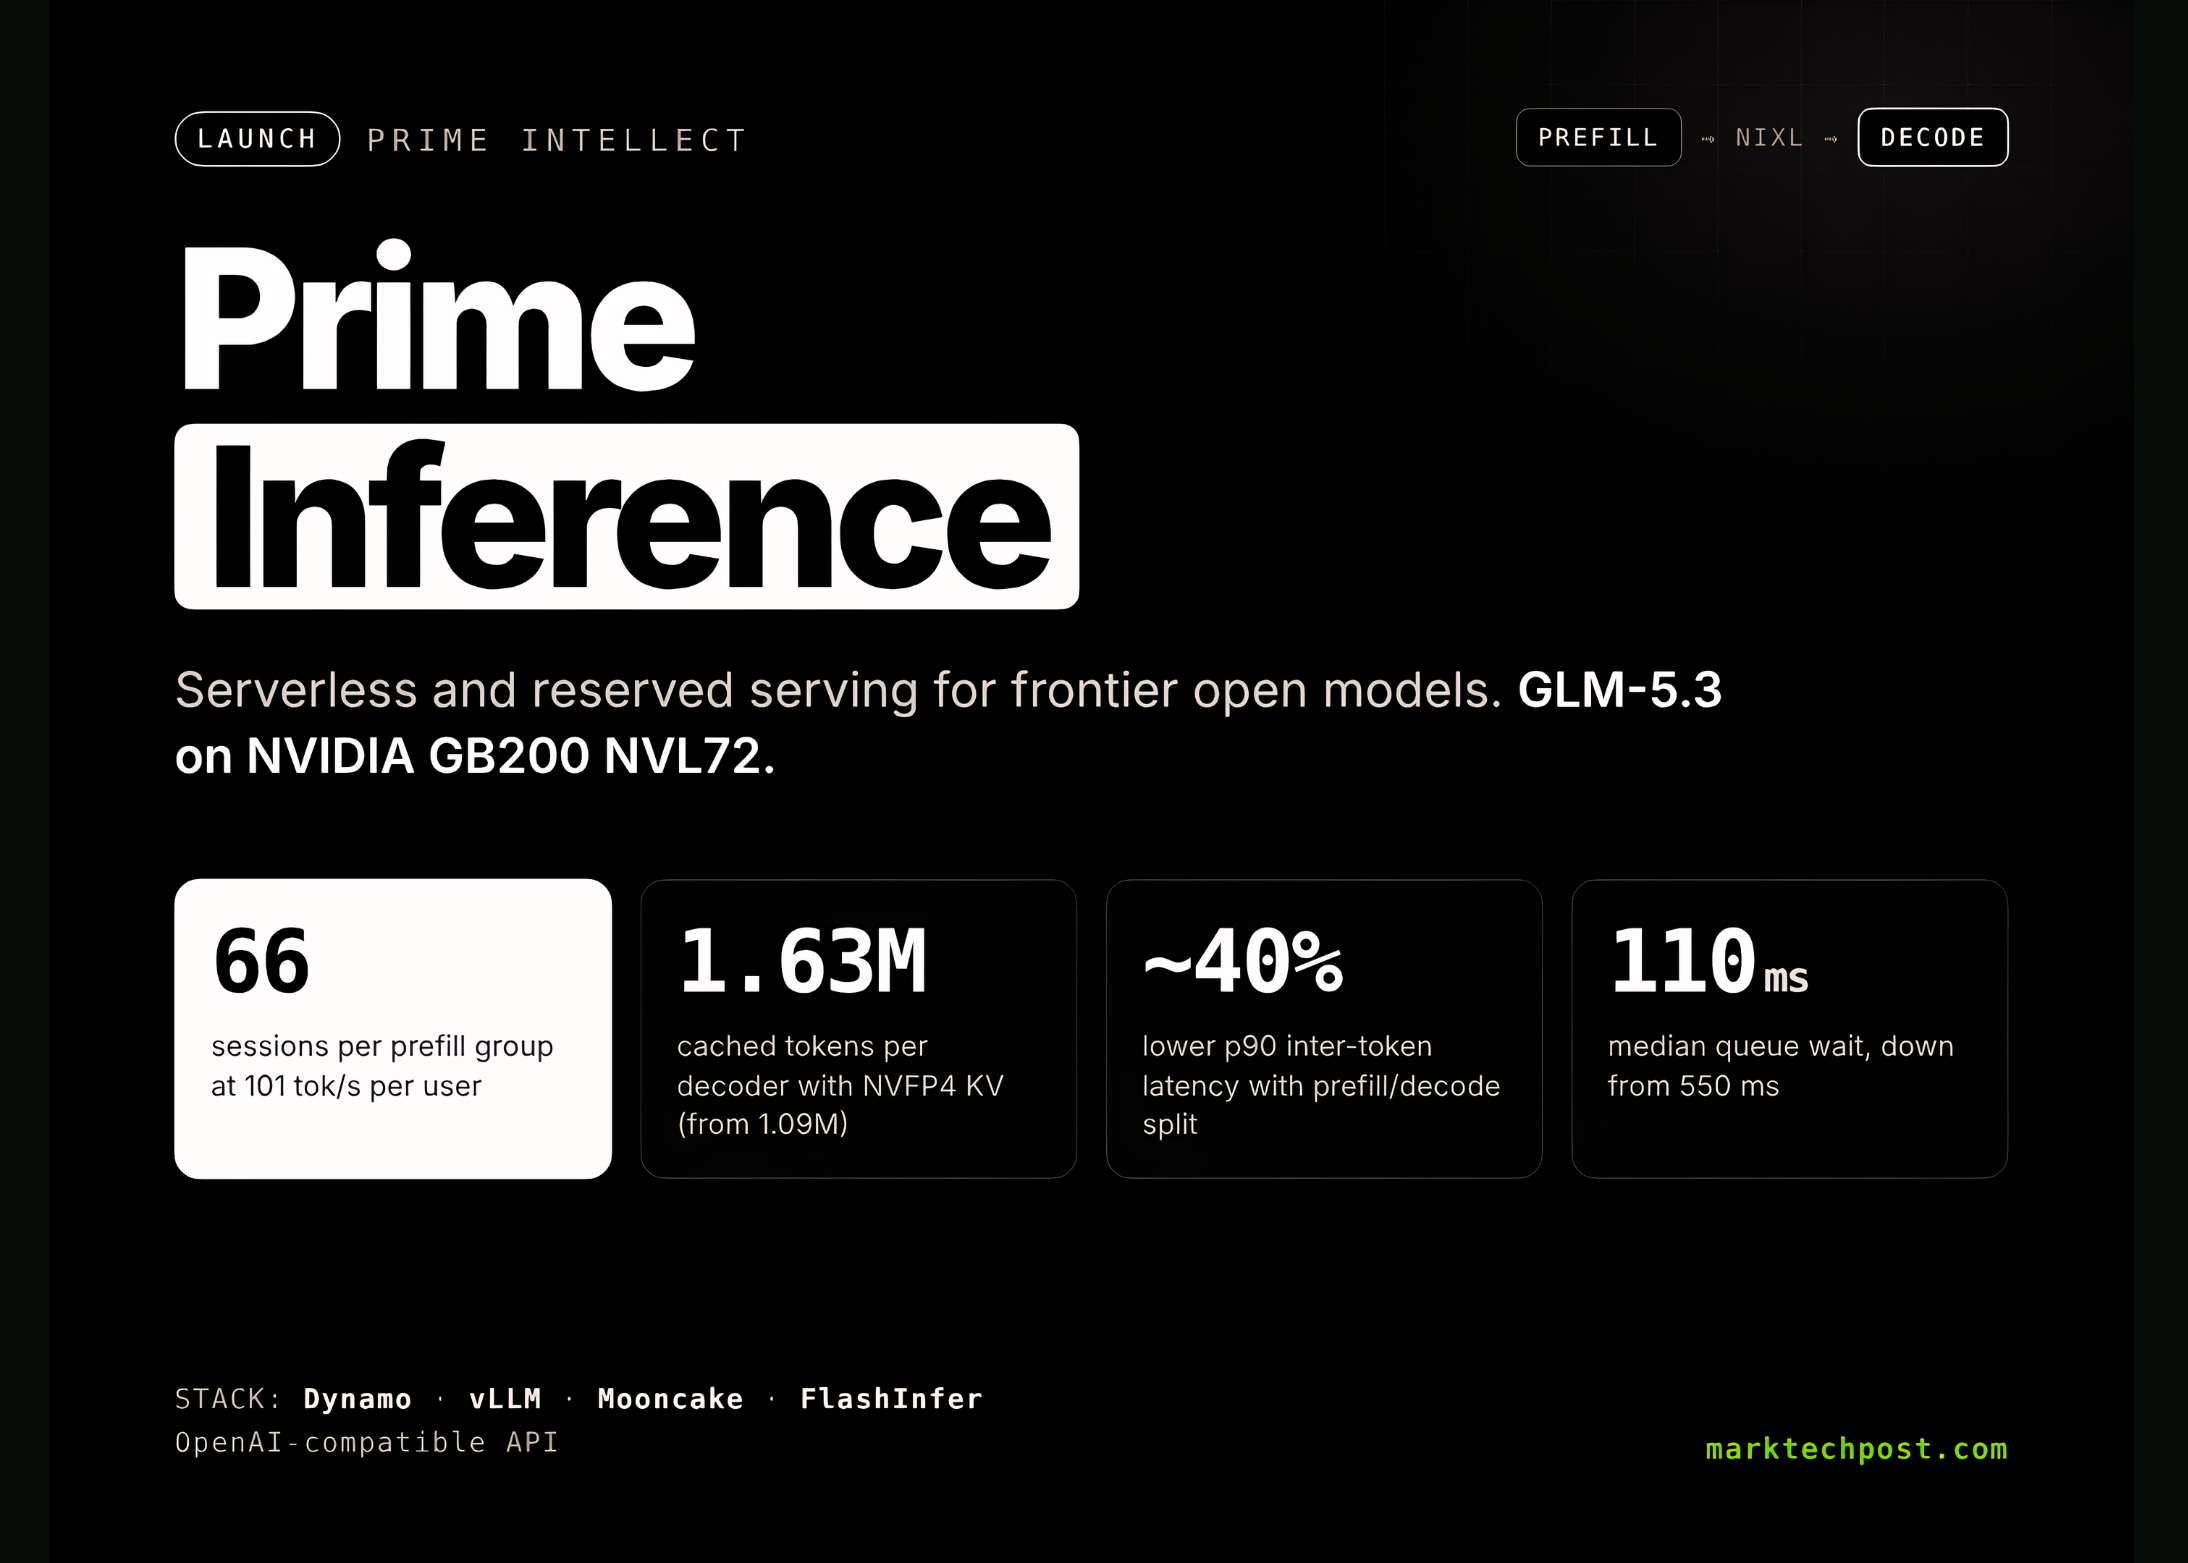
Prime Intellect has launched Prime Inference , a serving platform for frontier open-source models. It offers serverless endpoints and reserved capacity on Prime’s own GPUs across multiple datacenters. Before public release, it processed nearly a trillion tokens per day internally. That traffic came from RL rollouts, synthetic data generation, evaluations and long-running coding agents. What is Prime Inference? Prime Inference is the serving layer of Prime Intellect’s open training stack. The company already ships post-training tools such as prime-rl, verifiers and sandboxes. Serving closes that loop: deployed models generate production traces that can feed back into training. Prime reports its GLM-5.3 endpoint ranks among the fastest on OpenRouter. It also cites a near-zero tool-call error rate and 100% uptime since launch. Two modes: serverless endpoints for variable demand, reserved capacity for sustained workloads. OpenAI compatible: point any OpenAI SDK at https://api.pinference.ai/api/v1 ( docs ). Uptime: automatic failover across datacenters routes traffic to healthy deployments. Hardware: NVIDIA Blackwell today, with Vera Rubin listed as coming soon. Billing: unified billing with team-level usage tracking. Per-model pricing is not yet fully published in the docs. How the serving stack works The stack combines NVIDIA Dynamo , vLLM , Mooncake and FlashInfer . It was built with Inferact and NVIDIA, and fixes are contributed upstream. The target workload is agentic. A typical agent turn adds about 6K tokens to a 140K-token prompt. Prime benchmarks this mix with SemiAnaly
Source: MarkTechPost