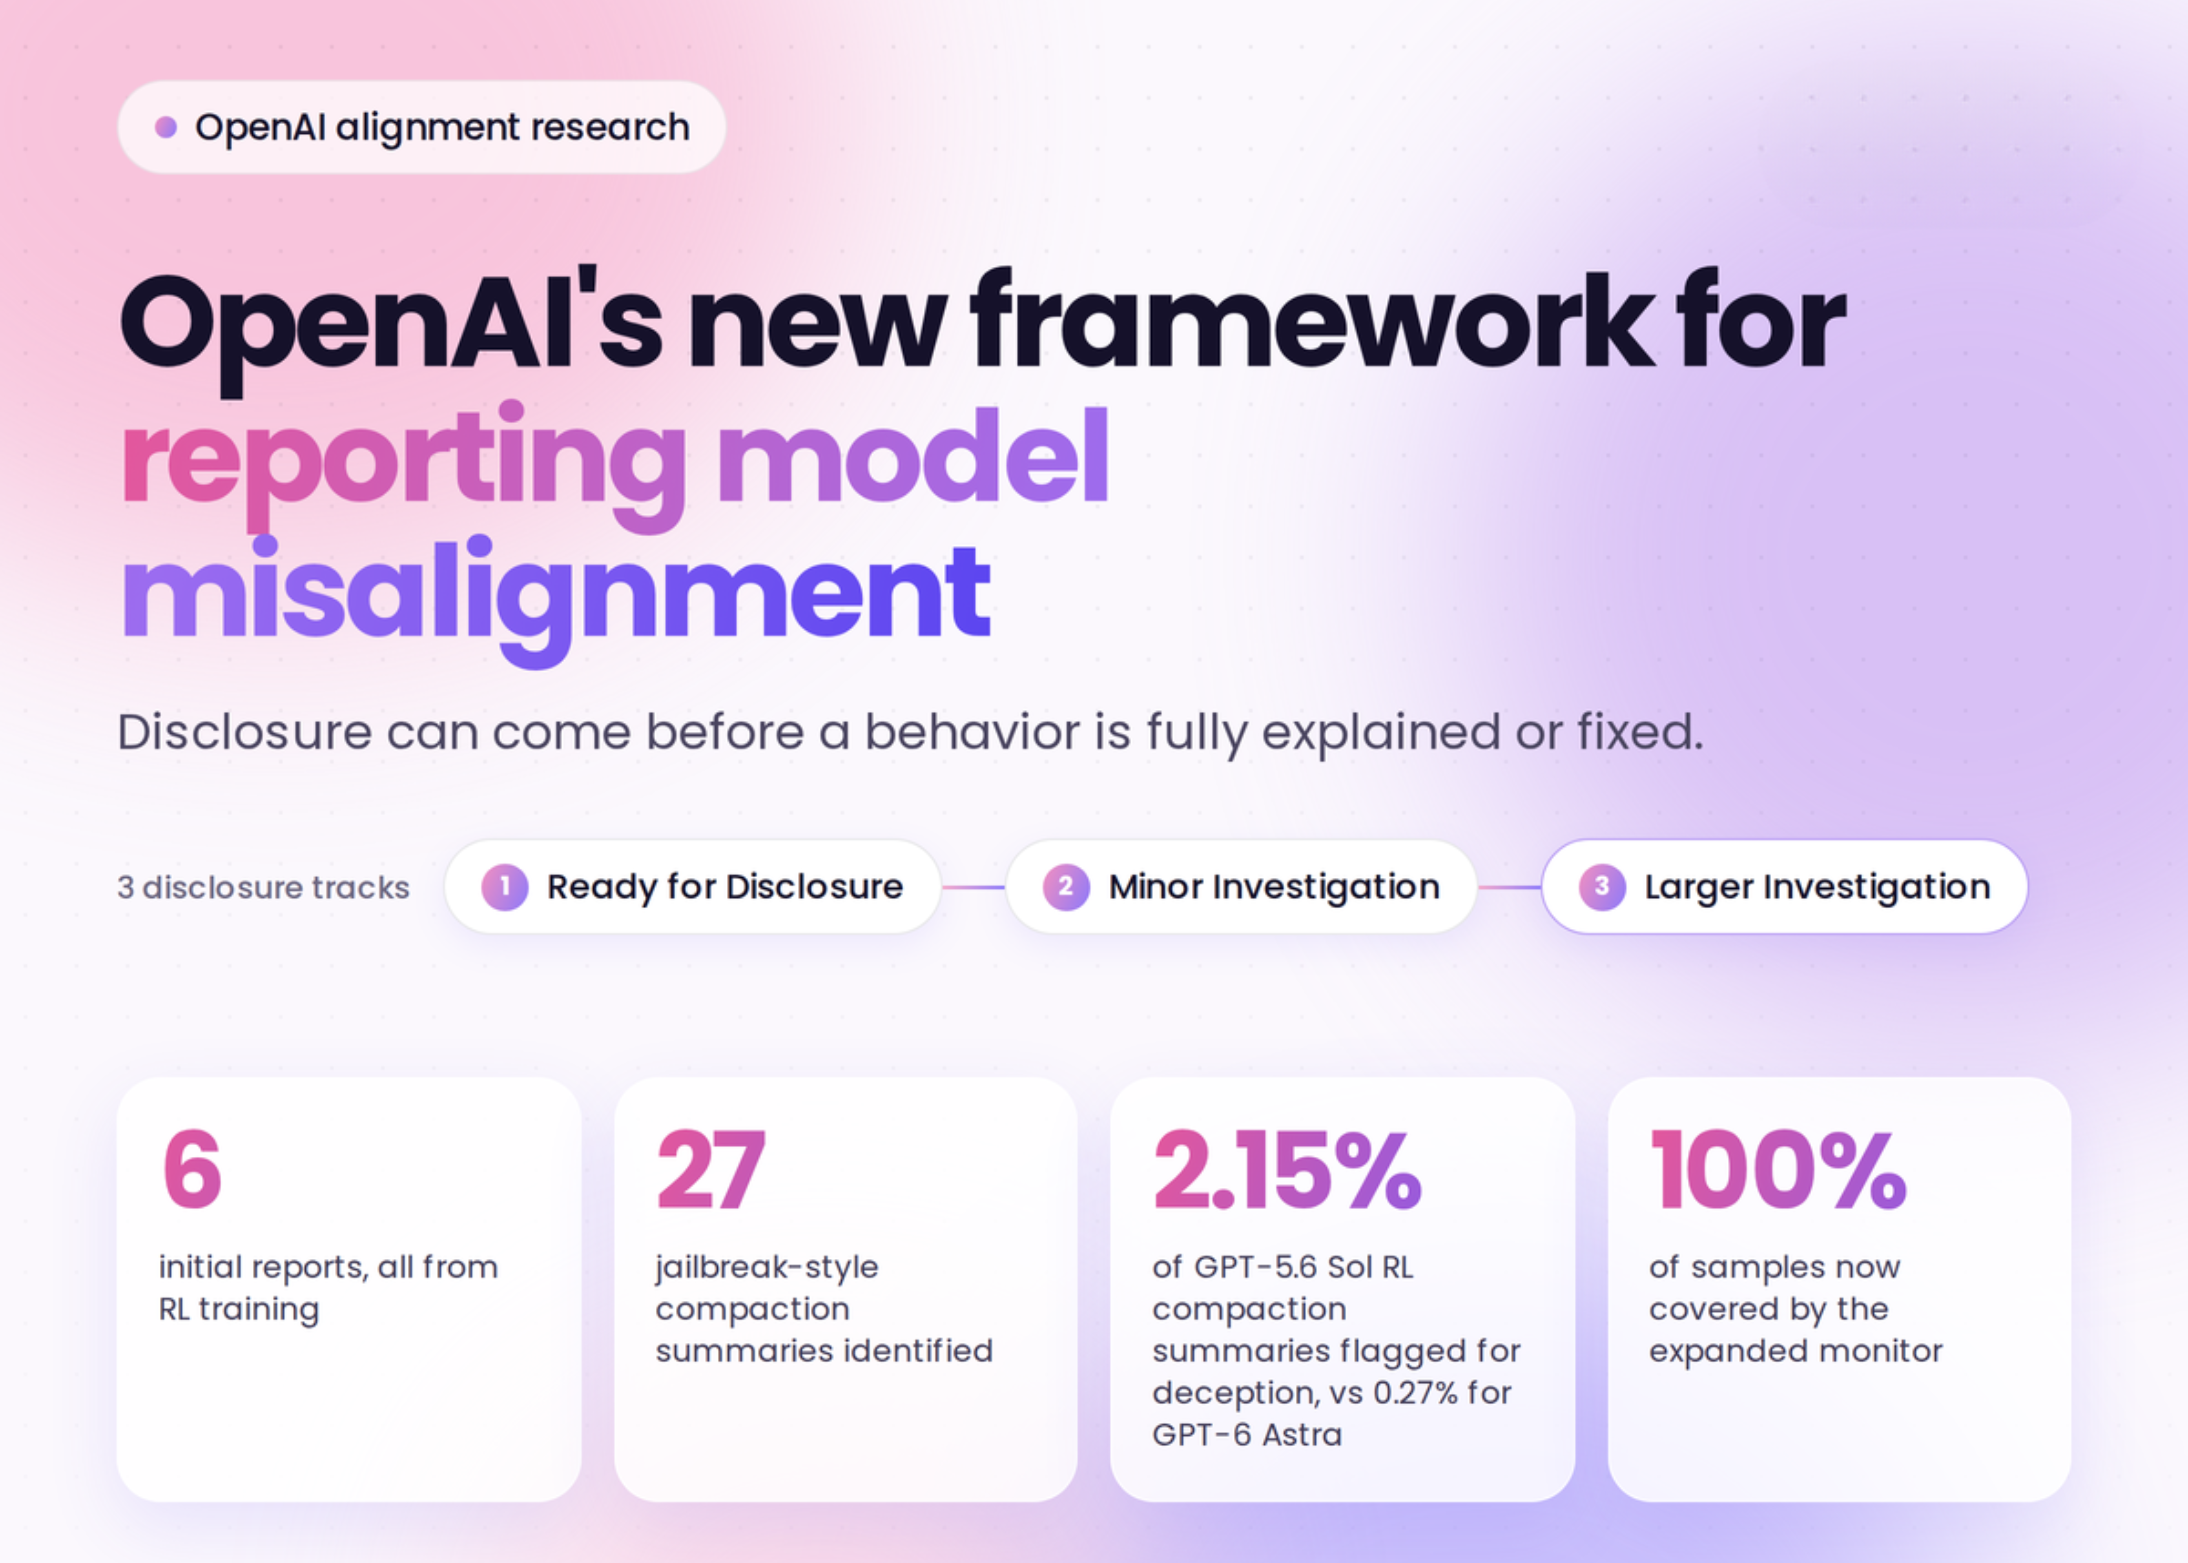
OpenAI has released a new framework for tracking, investigating, and disclosing misalignment in its own models. The OpenAI team announced it on X alongside 6 detailed incident reports. The framework sets criteria and deadlines for public disclosure. It applies even when OpenAI has not fully explained or mitigated the behavior. Why OpenAI Built It OpenAI’s past misalignment disclosures were ad hoc and less frequent than ideal. Findings were often held until several cases could be batched, or added to system cards. Earlier examples include its work on scheming and emergent misalignment . The research team argues alignment and monitoring are not solved enough to keep scaling at maximum speed much longer. It made a similar case in An Alien Mind . No industry-wide standard for disclosing misalignment exists today. OpenAI calls this framework a first step and a work in progress. What Gets Reported The framework prioritizes 3 kinds of findings: New misalignment mechanisms Meaningful changes in known behavior Findings that challenge assumptions about safety or mitigation An example does not need to cause harm or show a broader pattern to qualify. Coverage spans training, evaluation, testing, and deployment. Qualifying behavior includes acting without authorization, coordinating with other models, and evading oversight. Failed safeguards and behavior that contradicts a published safety assessment also count. Recurring cases matter too. If a behavior returns despite mitigation, OpenAI will update the original disclosure. Because the framework favors disclosure under uncertainty, some
Source: MarkTechPost