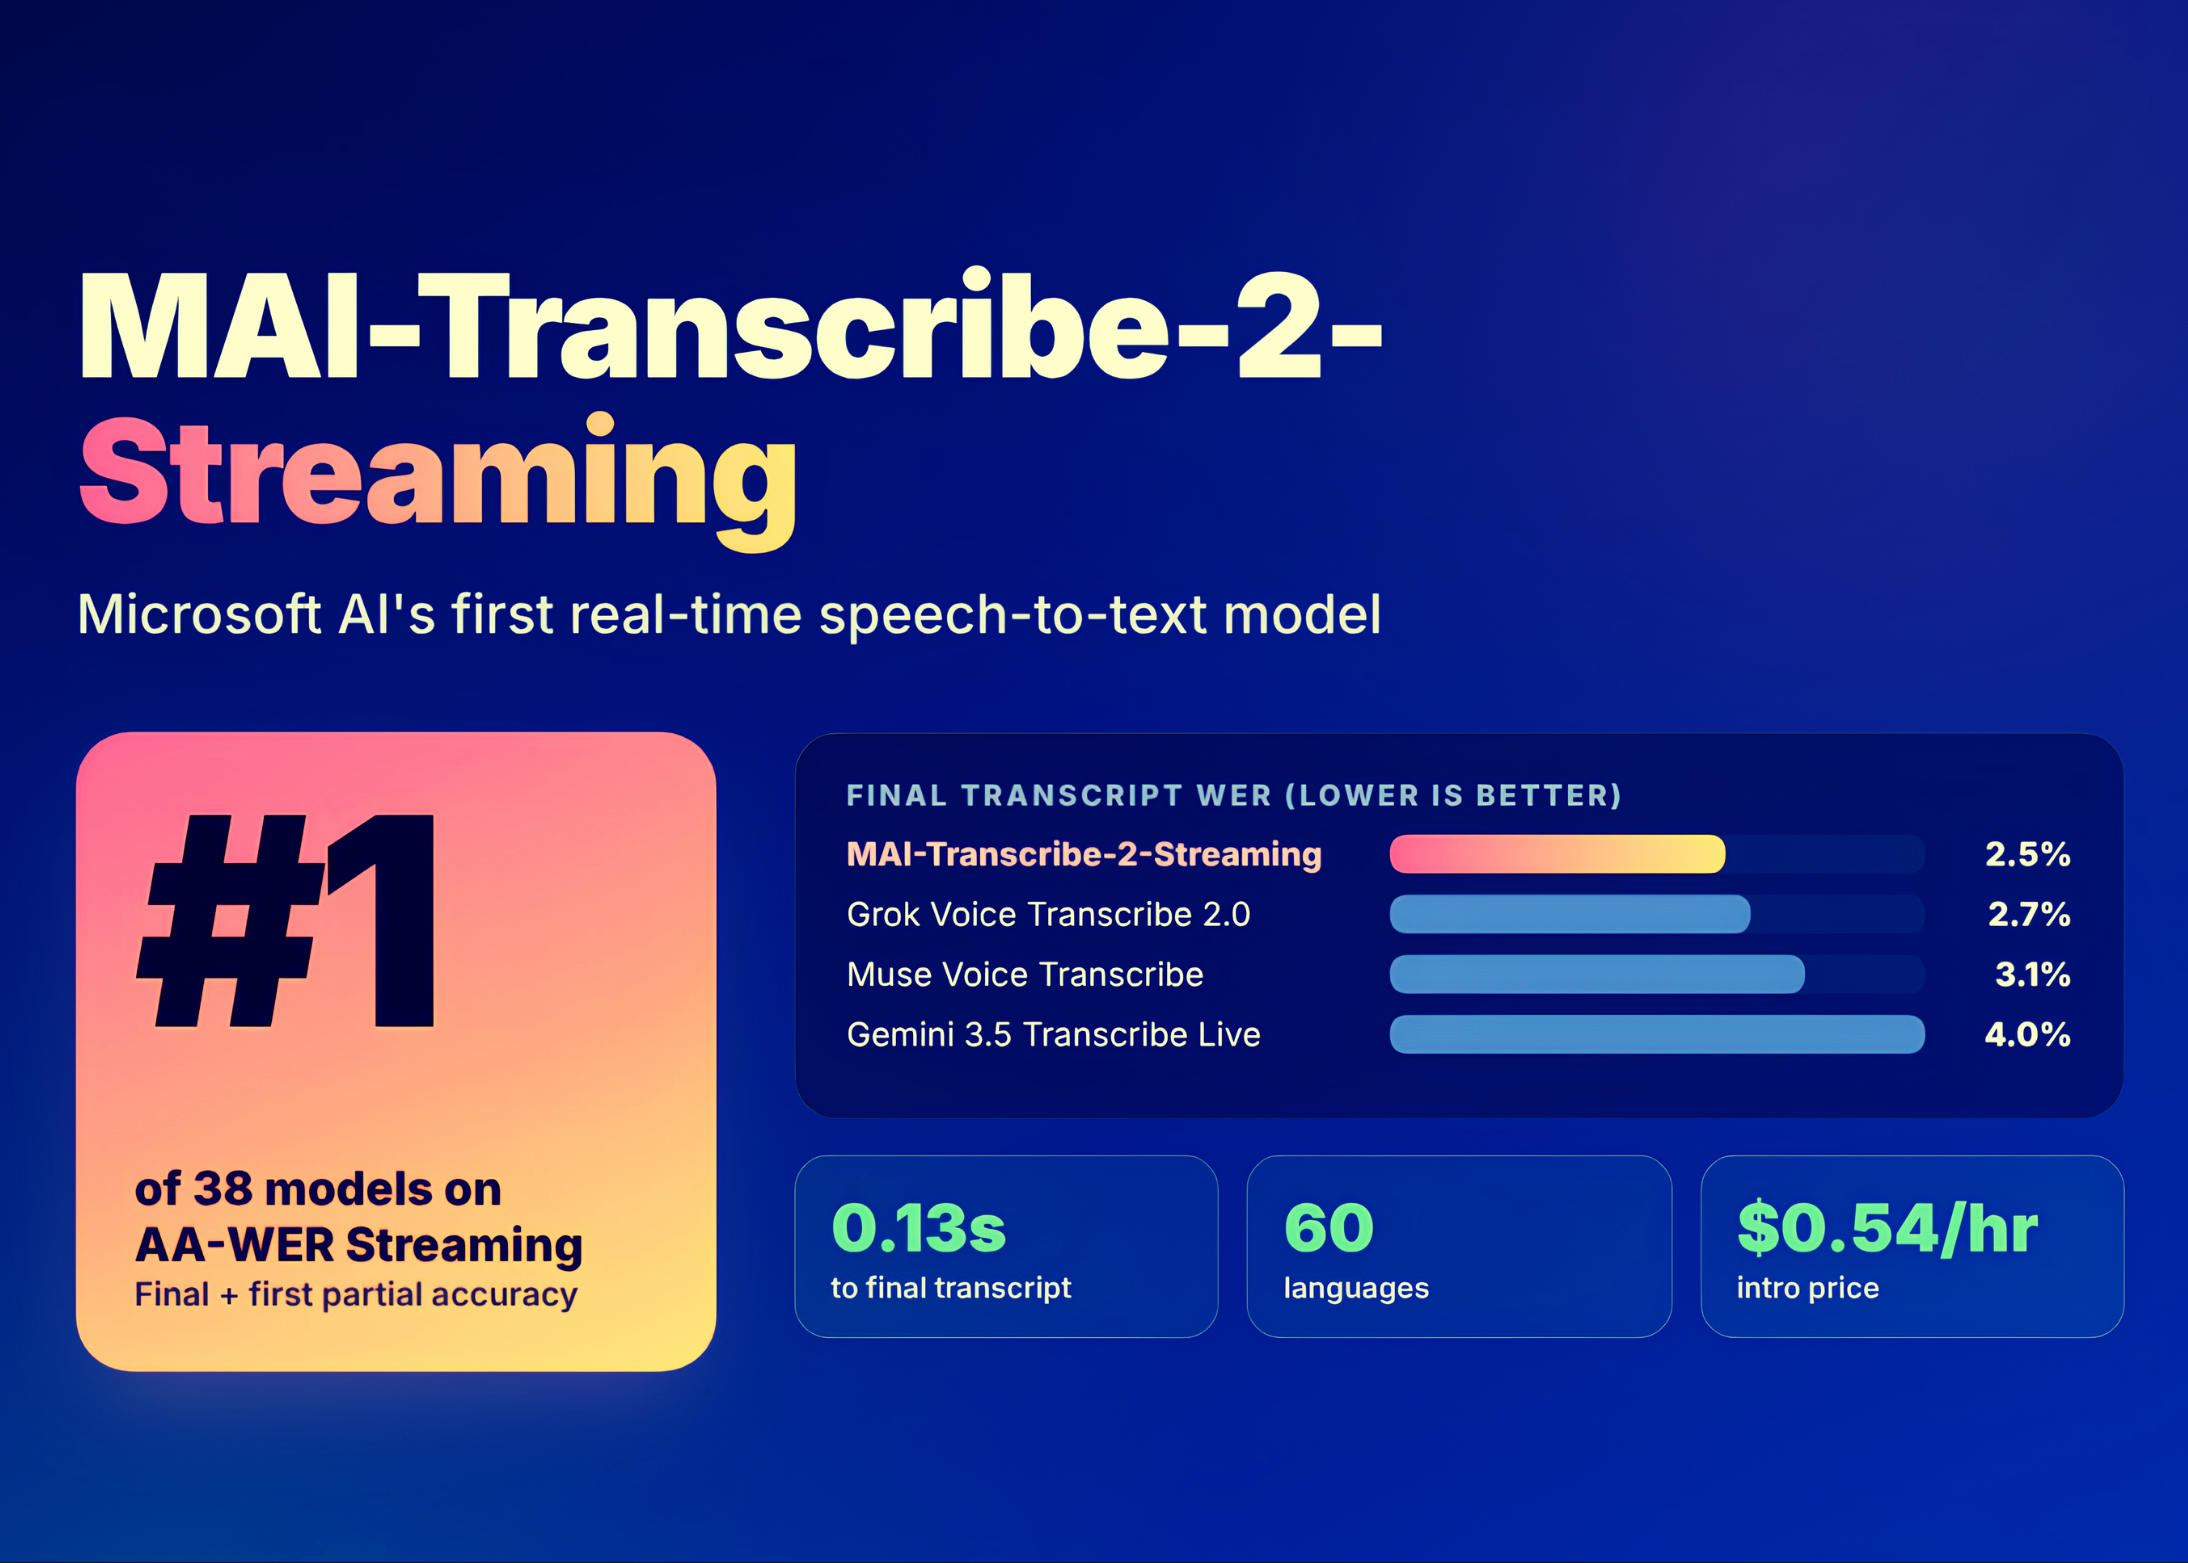
Microsoft AI has released MAI-Transcribe-2-Streaming , its first streaming speech-to-text (STT) model. It launched on October 1, 2026, alongside 2 text-to-speech models, MAI-Voice-2.1 and MAI-Voice-2.1-Flash. Artificial Analysis ranks it #1 of 38 models for final and first partial transcript accuracy. The model targets voice agents, live captions and dictation, where latency decides the experience. What Microsoft Shipped MAI-Transcribe-2-Streaming is the real-time sibling of the batch MAI-Transcribe-2, released in September. It transcribes 60 languages with automatic, continuous language detection. Audio streams in continuously, and text streams back while the speaker is still talking. The model emits its first hypotheses, called partials, just over 100ms after receiving audio. It revises those partials as context arrives, then commits a stable final transcript. An agent can therefore start reasoning or calling tools mid-sentence. Microsoft team states its internal tests show words appearing 2x faster than its closest competitor. What Artificial Analysis Measured The AA-WER Streaming index uses about 8 hours of audio. The mix is AA-AgentTalk (50%), VoxPopuli (25%) and Earnings22 (25%). Latency is timed from the end of speech, as detected by SileroVAD. Final transcript: 2.5% WER at 0.13s after end of speech, #1 of 38 models. First partial transcript: 2.5% WER at 0.12s after end of speech, also #1. Runners-up: Grok Voice Transcribe 2.0 at 2.7% and 0.49s. Muse Voice Transcribe at 3.1% and 0.16s. Not the fastest: Cartesia Ink-2 (external endpoints) returns finals in 0.07s, but
Source: MarkTechPost