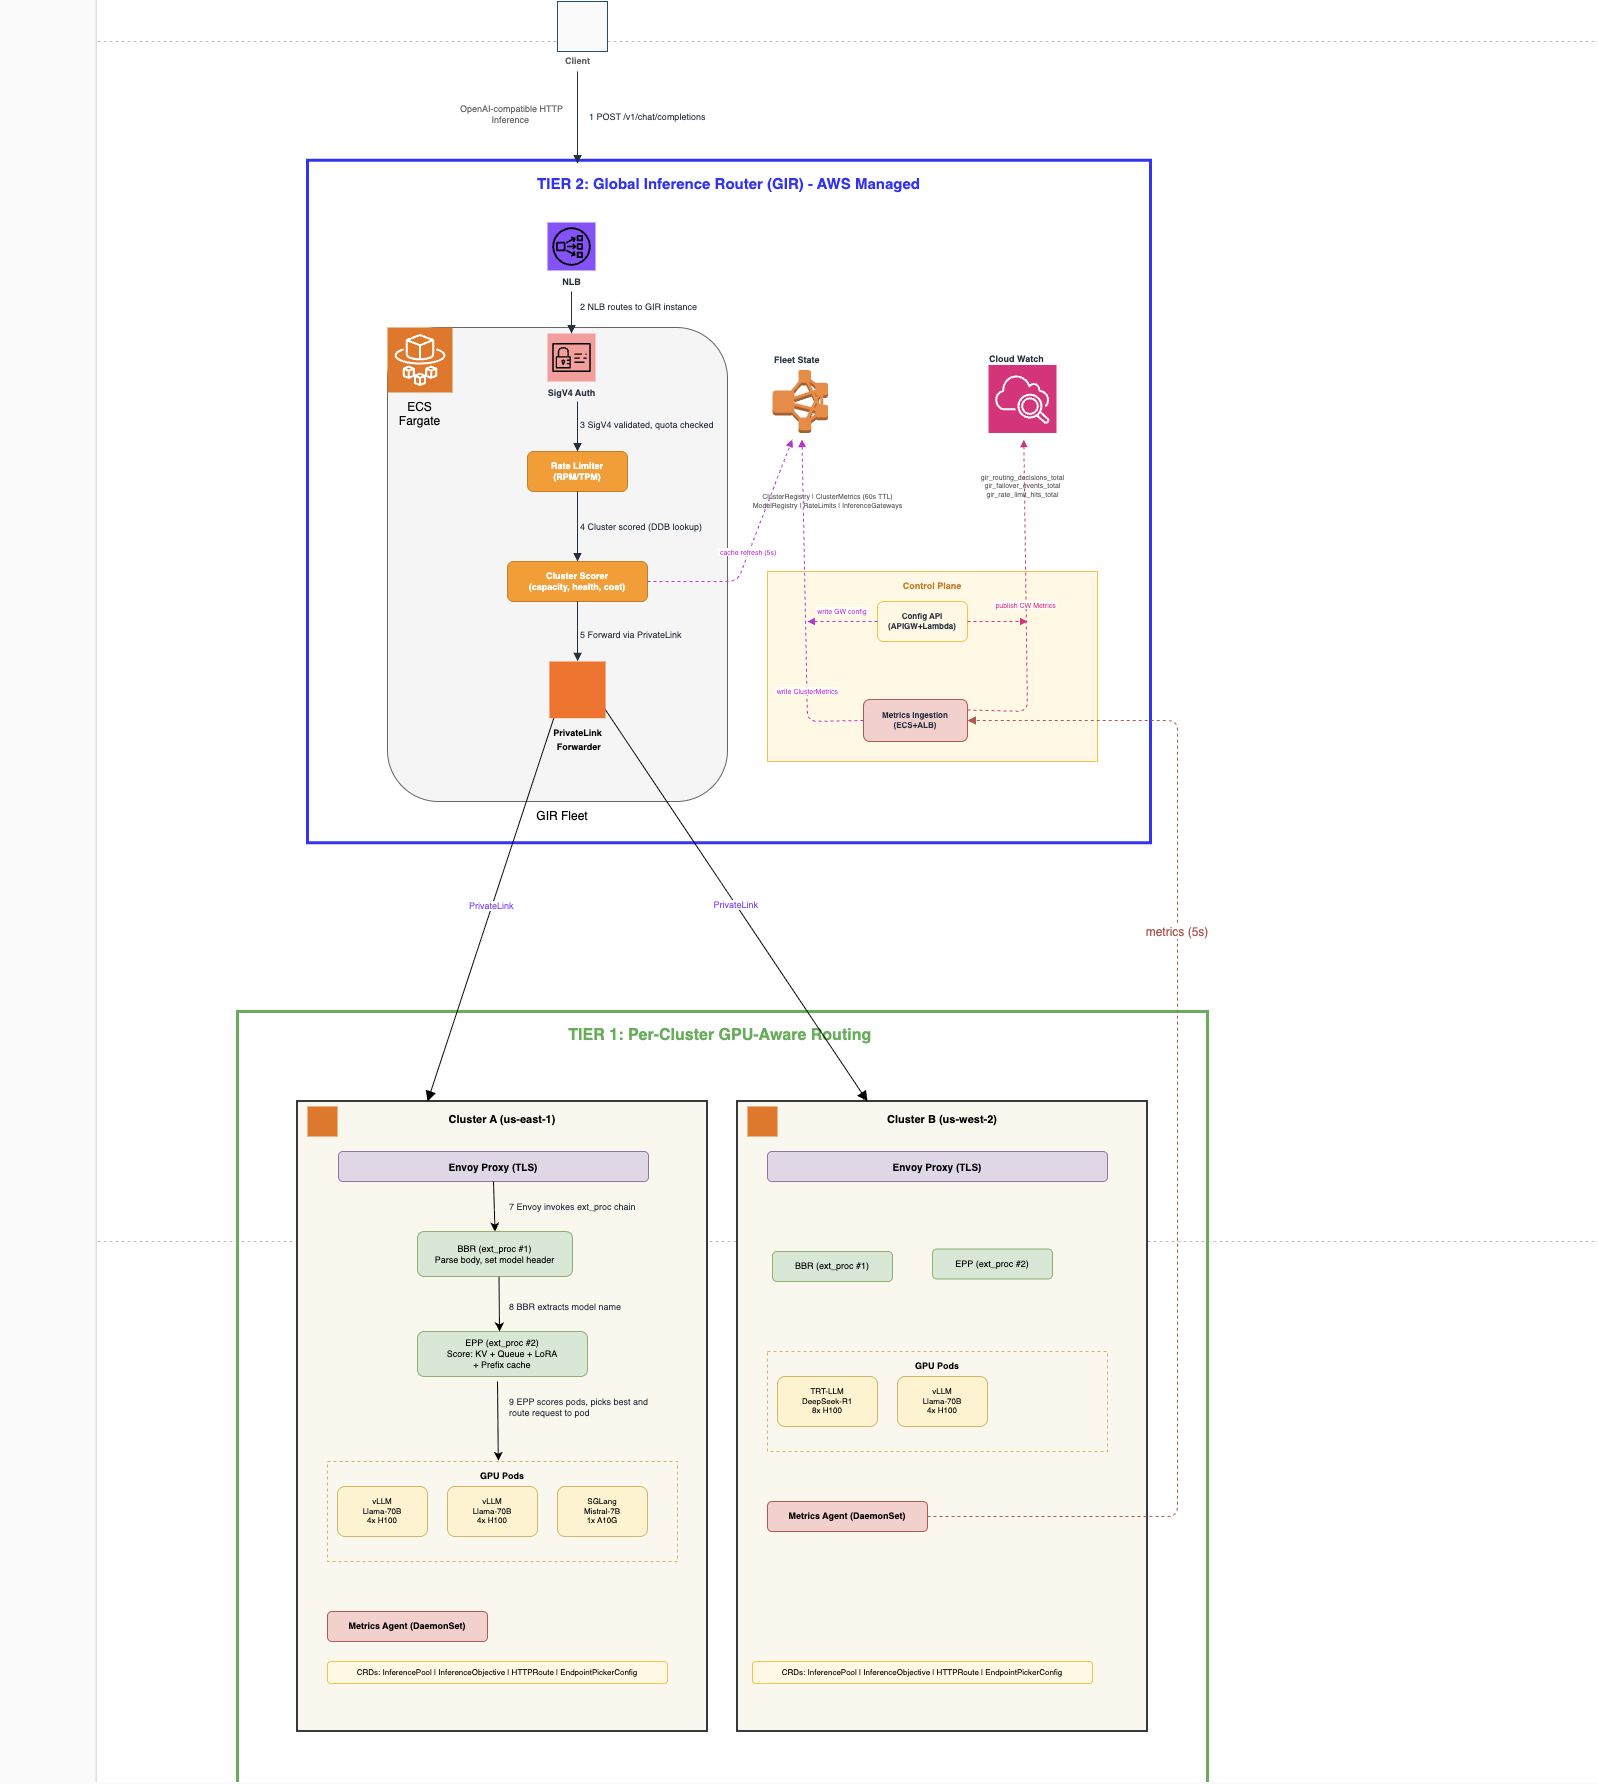
Eliminate GPU waste. Reduce first-token latency by up to 82%. Install one Kubernetes-native addon with zero application changes. The problem: Naive routing wastes your most expensive resource Running large language models (LLMs) at scale on GPU clusters is expensive. The default Kubernetes load balancers are making it worse. Round-robin and least-connections algorithms have no visibility into what’s happening inside your GPUs: which pods have saturated KV caches, which are mid-way through long-context generations, or which already have the LoRA adapter your request needs loaded in memory. The result? Round-robin routing causes requests to pile up behind busy pods while idle capacity remains unused. First-token latency spikes to 4+ seconds during traffic bursts. GPU utilization becomes uneven and unpredictable. You over-provision to compensate. This burns money on GPUs that aren’t doing useful work. The solution: SageMaker HyperPod Inference Gateway Today, we’re excited to announce Amazon SageMaker HyperPod Inference Gateway. It is a Kubernetes-native, GPU-aware routing system that deploys as a single EKS managed addon on your existing HyperPod infrastructure. It uses real-time GPU signals to place every inference request on the best-suited pod, delivering lower latency with no changes to your model servers or client applications. “A chatbot user waiting 4.4 seconds for the first token now sees it in under 800 ms.” How it works: Two-tier architecture The Inference Gateway uses a two-tier design built entirely on Kubernetes-native primitives. Figure 1: Two-tier architecture o
Source: AWS Artificial Intelligence