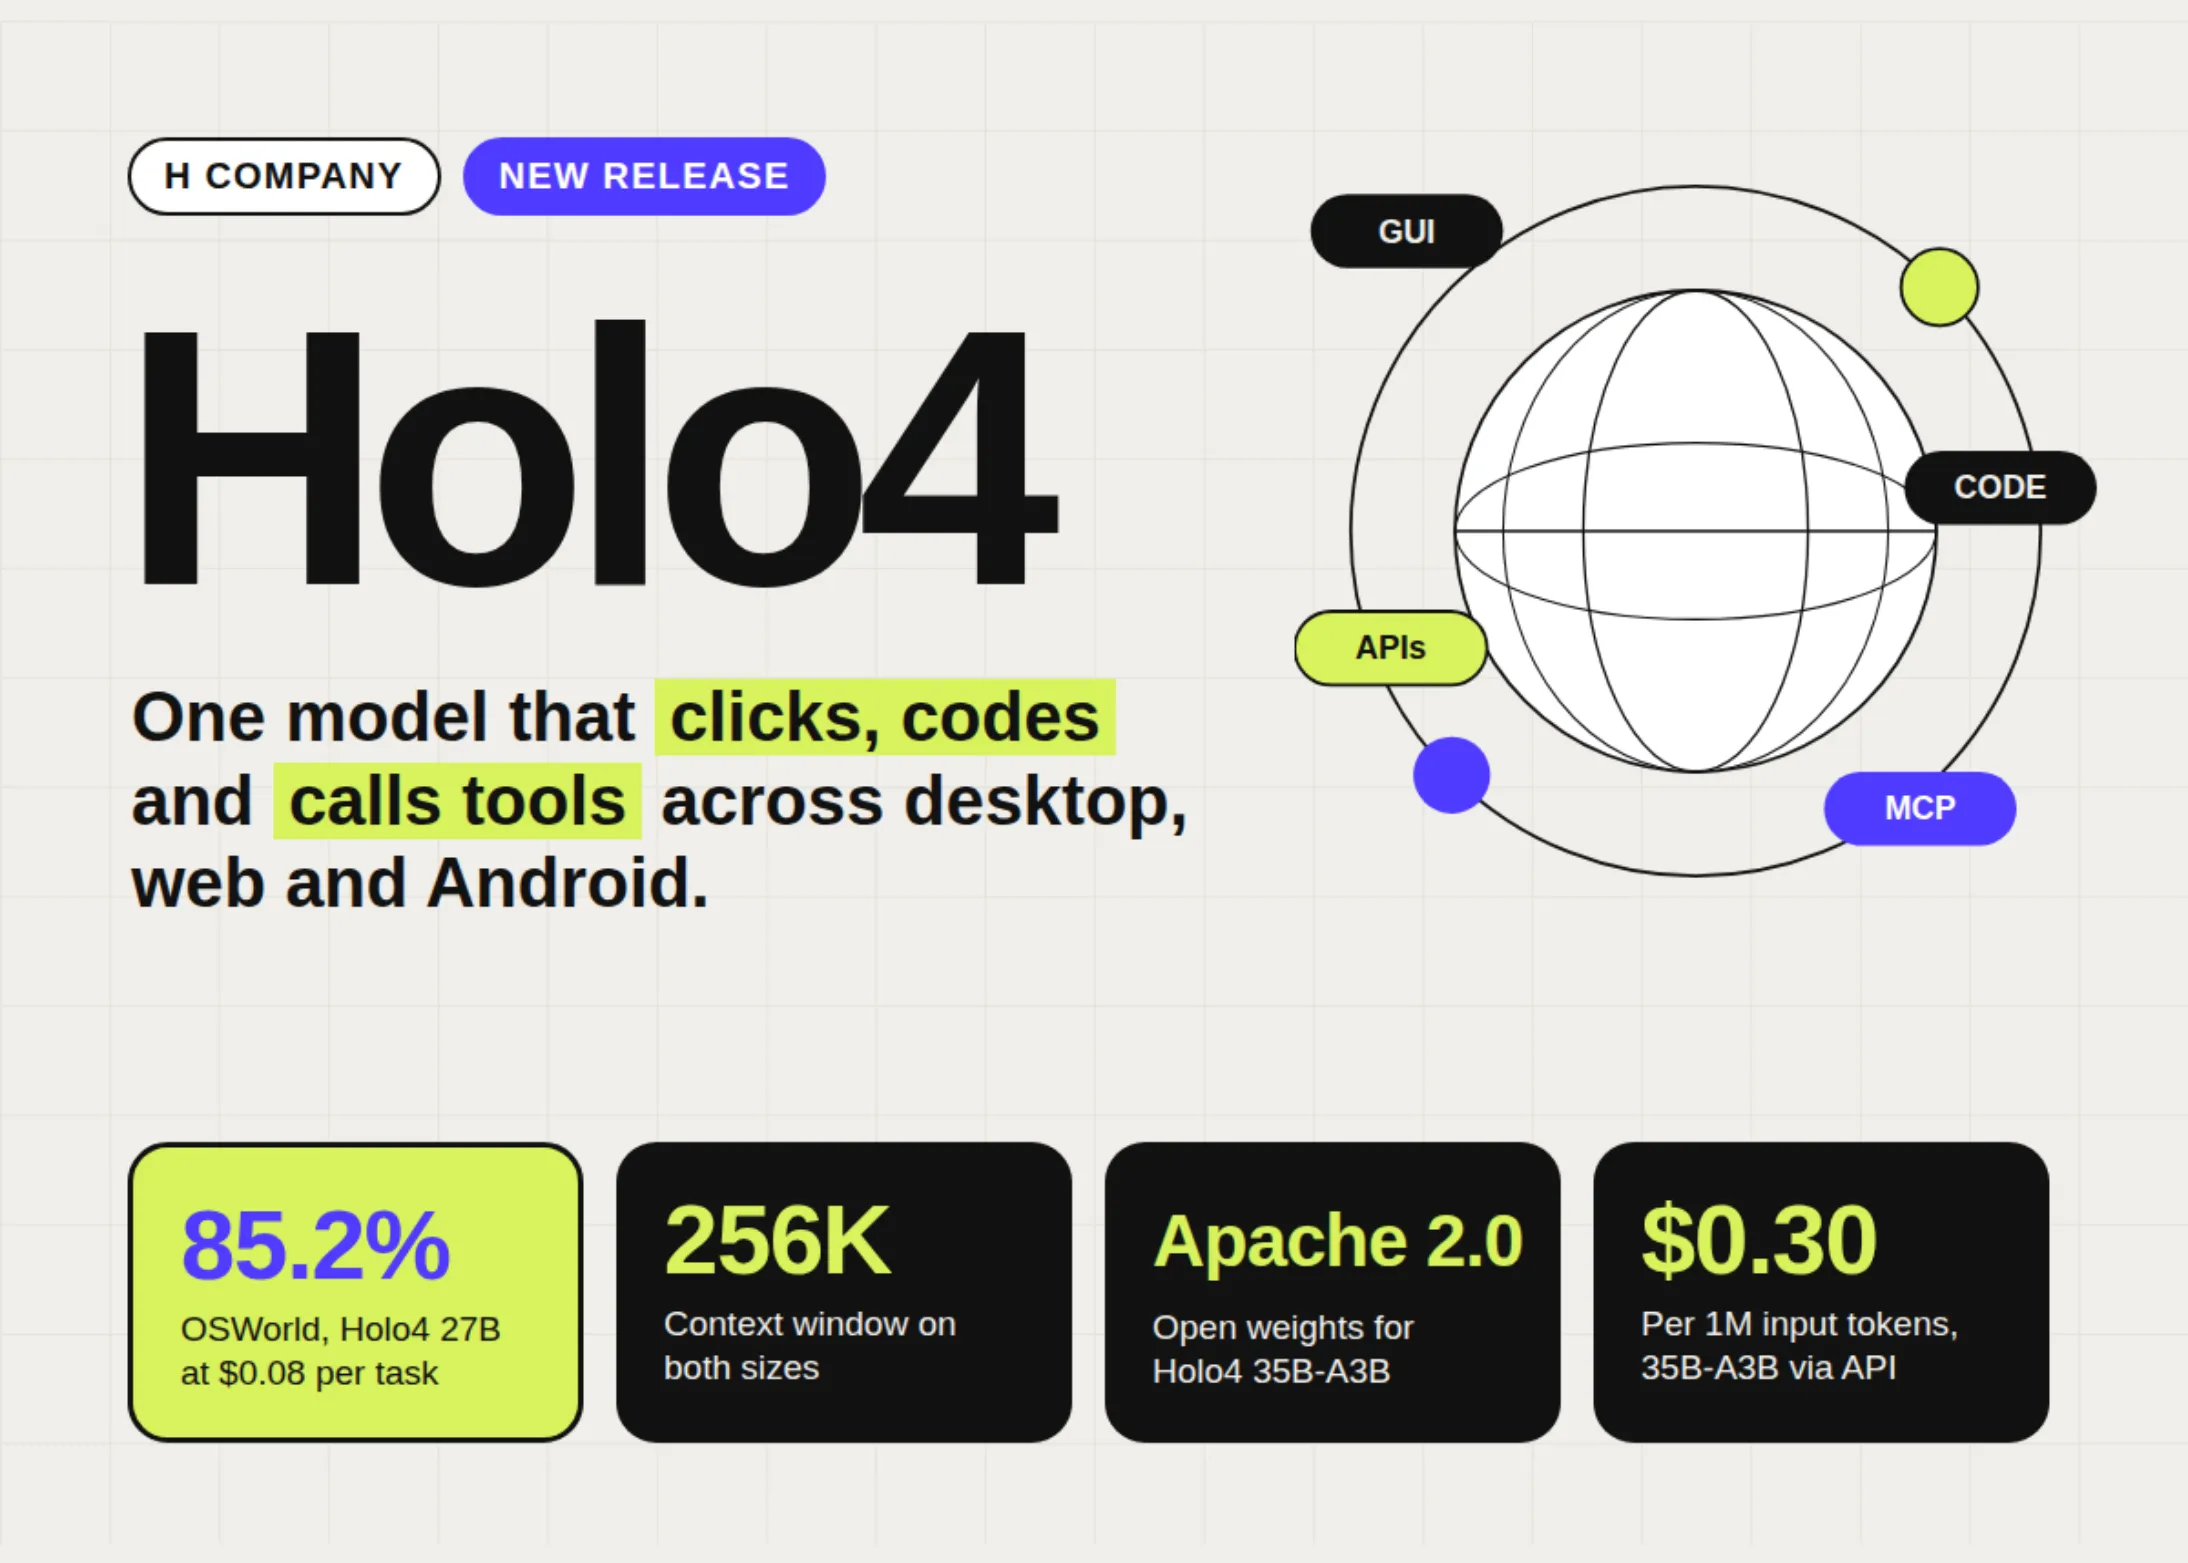
H Company has released Holo4 , a family of generalist computer-use models for AI agents. One set of weights clicks and types on screens. It also writes code and calls MCP or API tools. Holo4 ships in 2 sizes: Holo4 27B (dense) and Holo4 35B-A3B (Mixture of Experts, 3B active). Both serve a 256K context on the H Models API . Is it deployable? Yes. Holo4 35B-A3B ships Apache 2.0 weights for commercial self-hosting. Holo4 27B weights are CC BY-NC 4.0, so commercial use of 27B runs through the H Models API. What is Holo4 Holo4 is a vision-language model for computer use. Holo4 27B is fine-tuned from Qwen3.8-27B . Holo4 35B-A3B is built on Qwen3.6-35B-A3B . Both pair with H’s open hai-agents harness . The harness sends screenshots and tool results to the model. It then executes the requested clicks, typing, code and tool calls. H company targets a known gap. GUI-only agents fail without a screen. Tool-calling agents stall when an application has no API. Holo4 runs on desktop, web, Android, code sandboxes and business APIs. It is the same model, called the same way, on every platform. Benchmarks: Close to the Frontier, at a Fraction of the Cost Per H Company’s benchmark table , Holo4 27B scores 85.2% on OSWorld at $0.08 per task. Its Qwen3.8 27B base scores 84.3% at $0.22. On AndroidWorld, Holo4 27B reaches 85.1%. Long workflows show the remaining gap. On OSWorld 2.0, Holo4 27B scores 61.7% at $1.22 per task. Claude Opus 5.5 scores 81.8% at $8.48, per H’s figures. On AutomationBench, Holo4 27B scores 45.4% at $0.05 per task. It is important to note that frontier scores come from
Source: MarkTechPost