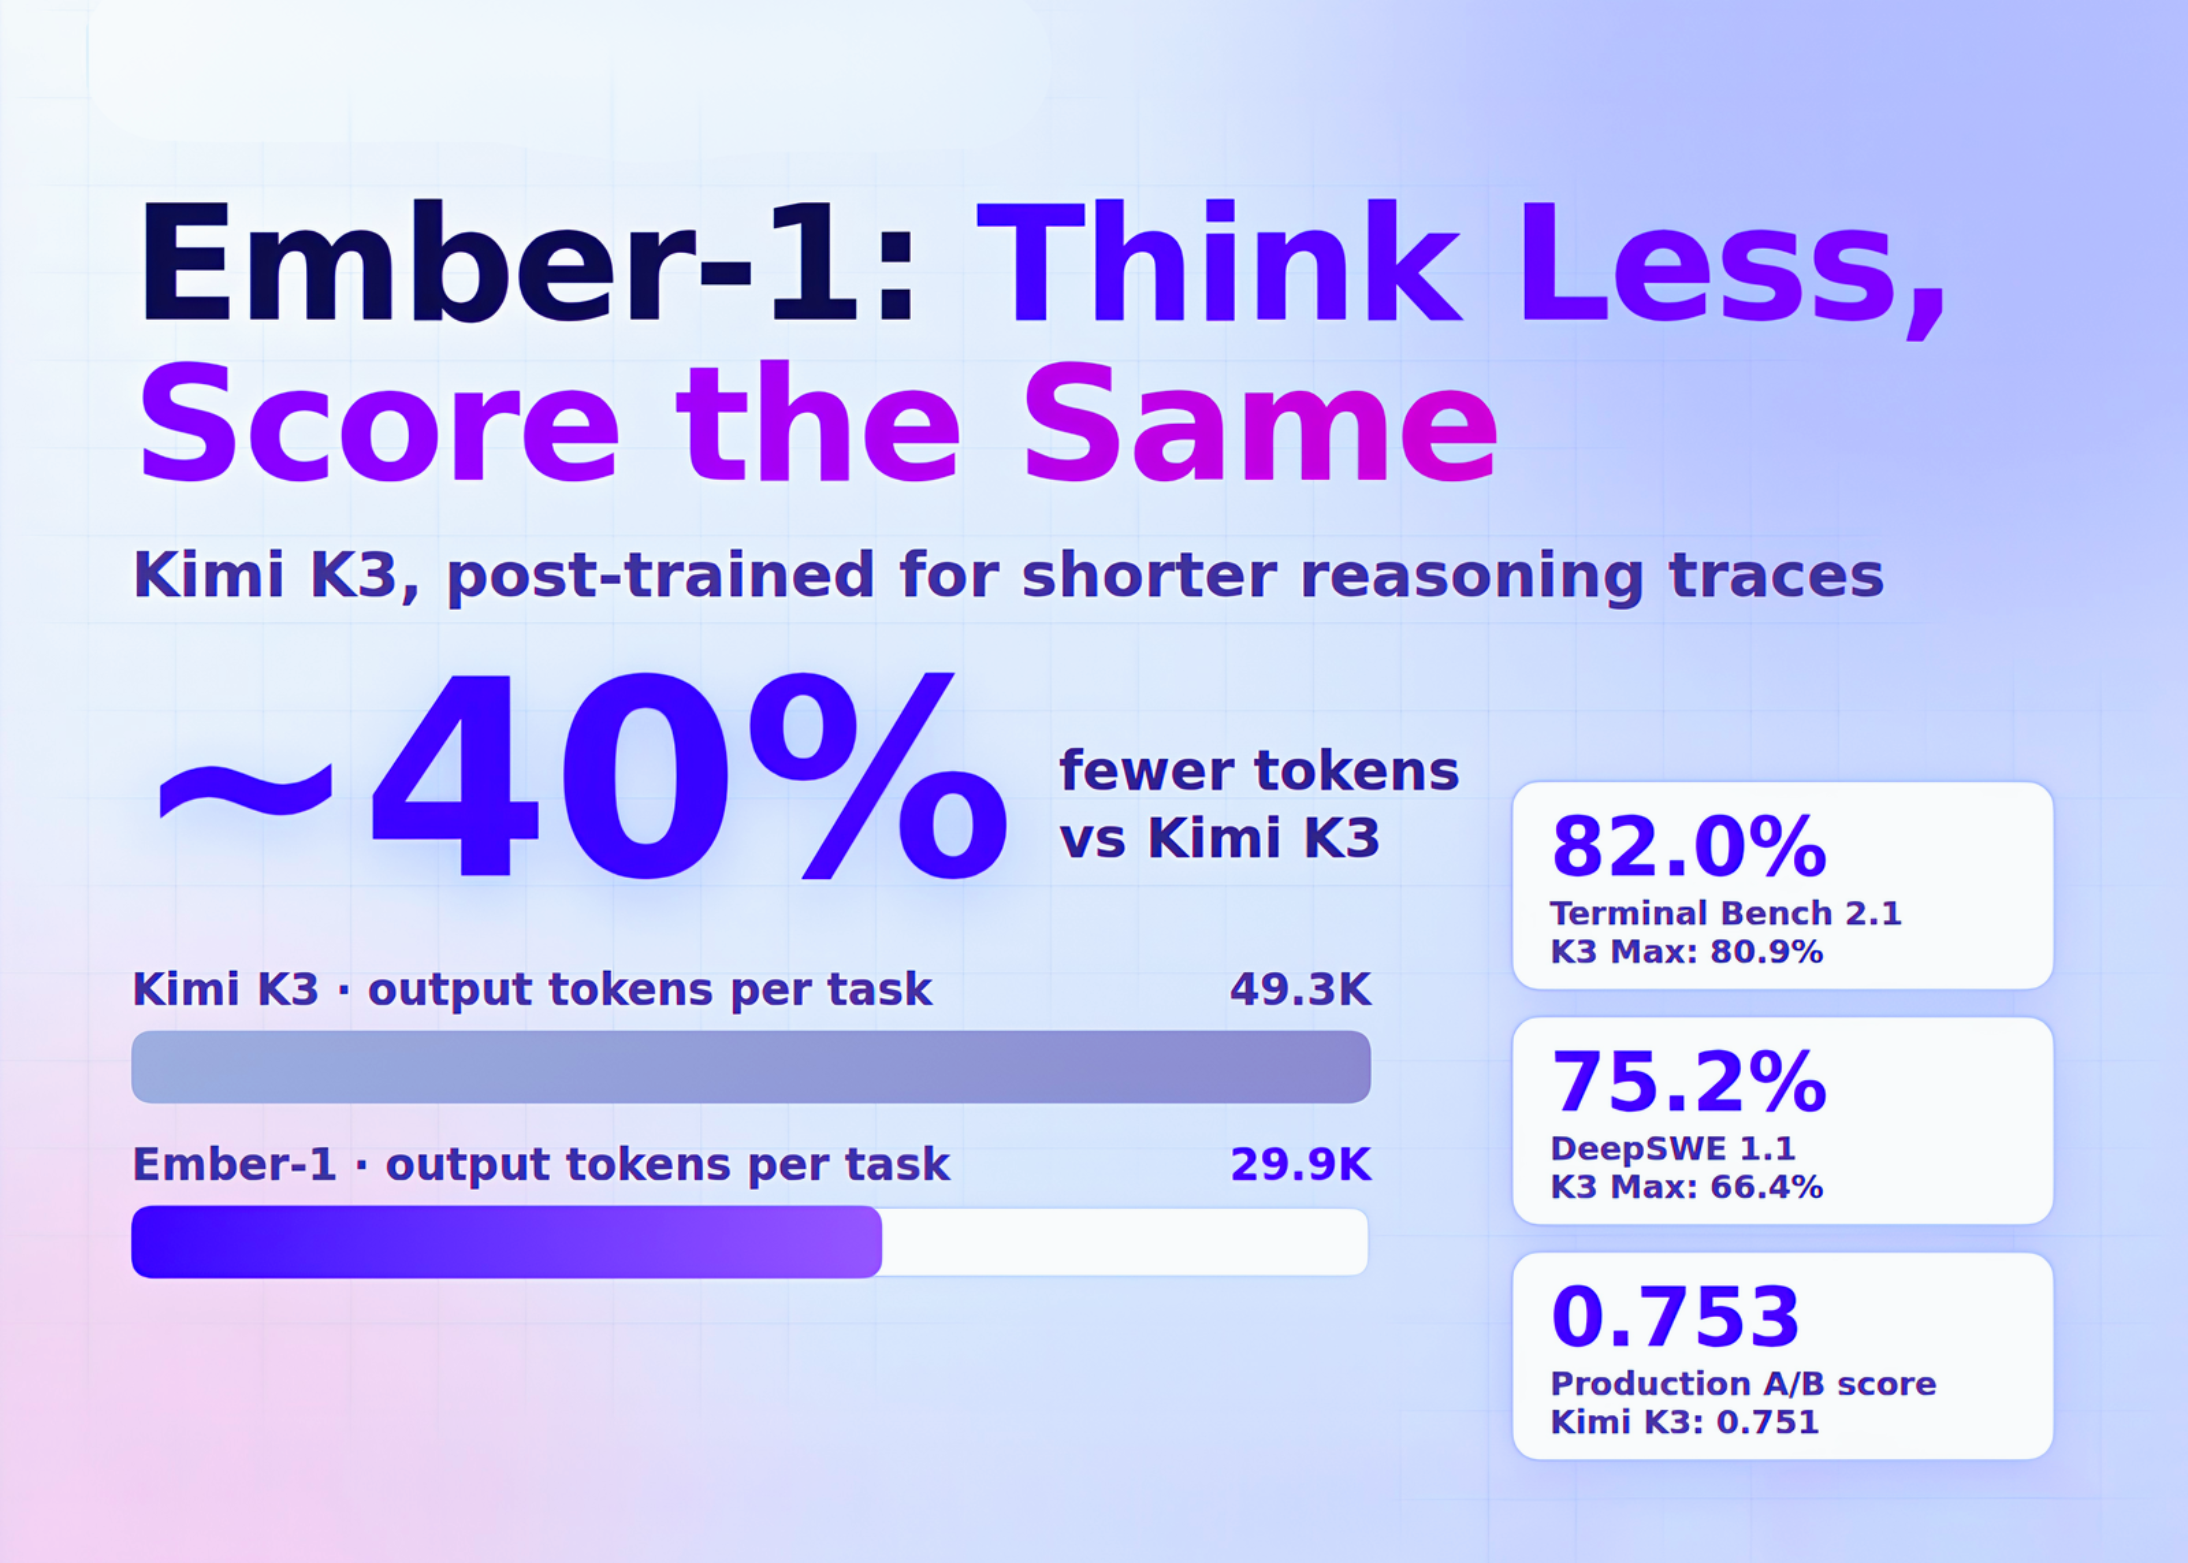
Fireworks AI has released Ember-1 , a specialized model from Fireworks Research built by post-training Moonshot AI’s open-weight Kimi K3 . Ember-1 learns to produce shorter reasoning traces while keeping task accuracy. This is different from lowering the reasoning effort setting at inference time. According to the Fireworks release post , Ember-1 delivers Kimi K3’s quality with about 40% fewer tokens. Is it deployable? Yes, but only through the Fireworks serverless API as a Research Preview. Fireworks has not released Ember-1’s weights, training code, or exact training algorithms, so self-hosting is not an option today. The Problem: Reasoning Models Think Too Much Fireworks team reports that reasoning models like Kimi K3 sometimes spend more than 90% of generated tokens on internal reasoning. That cost compounds in multi-turn agentic workloads. Each turn replays prior reasoning back to the model. Context grows roughly quadratically with the number of turns. Long traces from early turns get re-read, and re-billed, on every later call. Fireworks team explains how customers wanted K3’s coding capability at lower cost. Turning down K3’s reasoning effort did not solve it. Lower effort settings gave up too much quality. So the team trained the model to reason more efficiently instead. How Fireworks Research Built Ember-1 Not all of K3’s reasoning is waste. Some of it is useful self-reflection, like revisiting an assumption or reacting to feedback. Ember-1 keep that behavior while cutting redundant reasoning and unproductive loops. The training collection spans mathematics, coding
Source: MarkTechPost