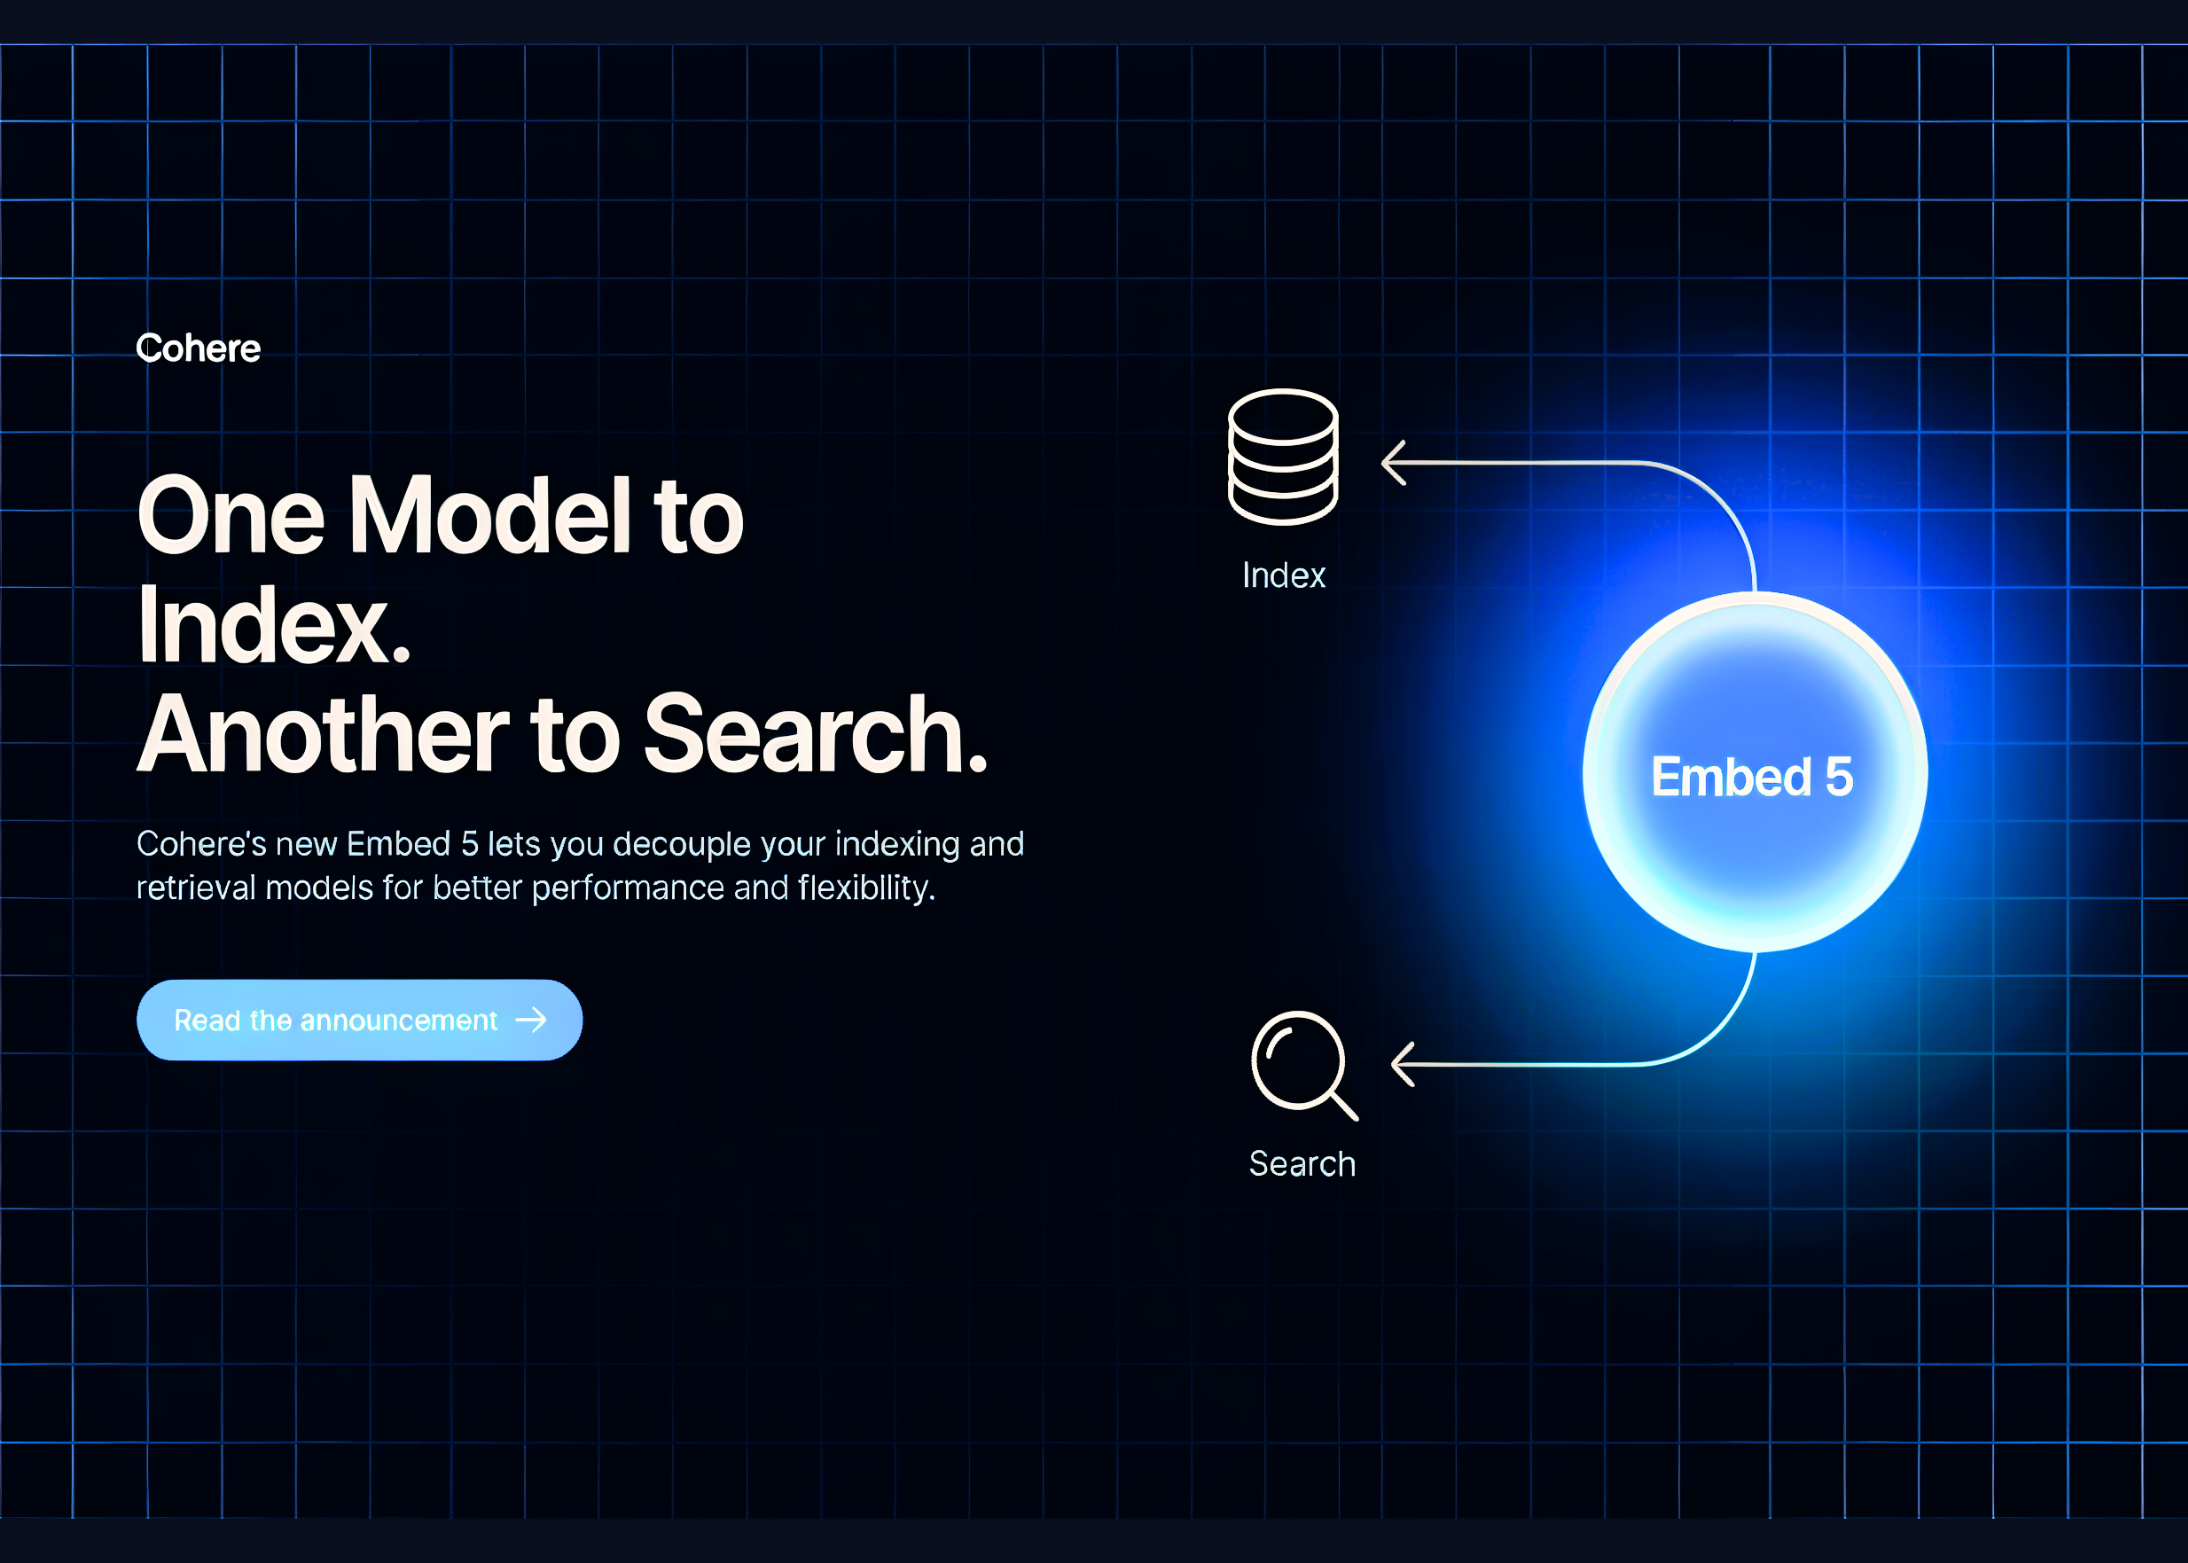
Cohere has released Embed 5 , a new embedding model family. It targets enterprise search, RAG, and agentic retrieval. The model family ships in 2 tiers. Embed 5 Pro targets maximum retrieval quality. Embed 5 Fast targets latency and cost on the live query path. Both accept text, images, and fused text plus image inputs. Both cover 100+ languages and read up to 128K tokens. The key design choice: Pro and Fast share 1 embedding space. You can index with one and query with the other. Is it deployable today? Yes, both tiers are generally available on the Cohere API and Model Vault , Microsoft Foundry , and Amazon SageMaker . Private VPC or on-prem serving runs through vLLM. What Cohere Shipped The API model IDs are embed-v5.0-pro and embed-v5.0-fast , per Cohere’s model docs . Both output 2048, 1536, 1024, 768, 512, or 256 dimensions, with 2048 as default. Embeddings come back as float, int8, or binary. Pro costs $0.12 per 1M text tokens. Fast costs $0.08. Image inputs cost $0.40 per 1M tokens on both. Embed 5 can embed a page image directly. It can also fuse an image with its metadata into a single vector. That is important for scanned pages, slide decks, schematics, and charts, where text extraction drops information. Pro and Fast: One Index, Two Query Paths Cohere tested every corpus and query pairing across 40 development datasets. Normalized to Pro plus Pro at 100, a Pro index queried with Fast scored 98.4. An all-Fast setup scored 96.6. Cohere’s recommended pattern is to index with Pro and query with Fast. One constraint: both sides must use the same output dimension. The
Source: MarkTechPost