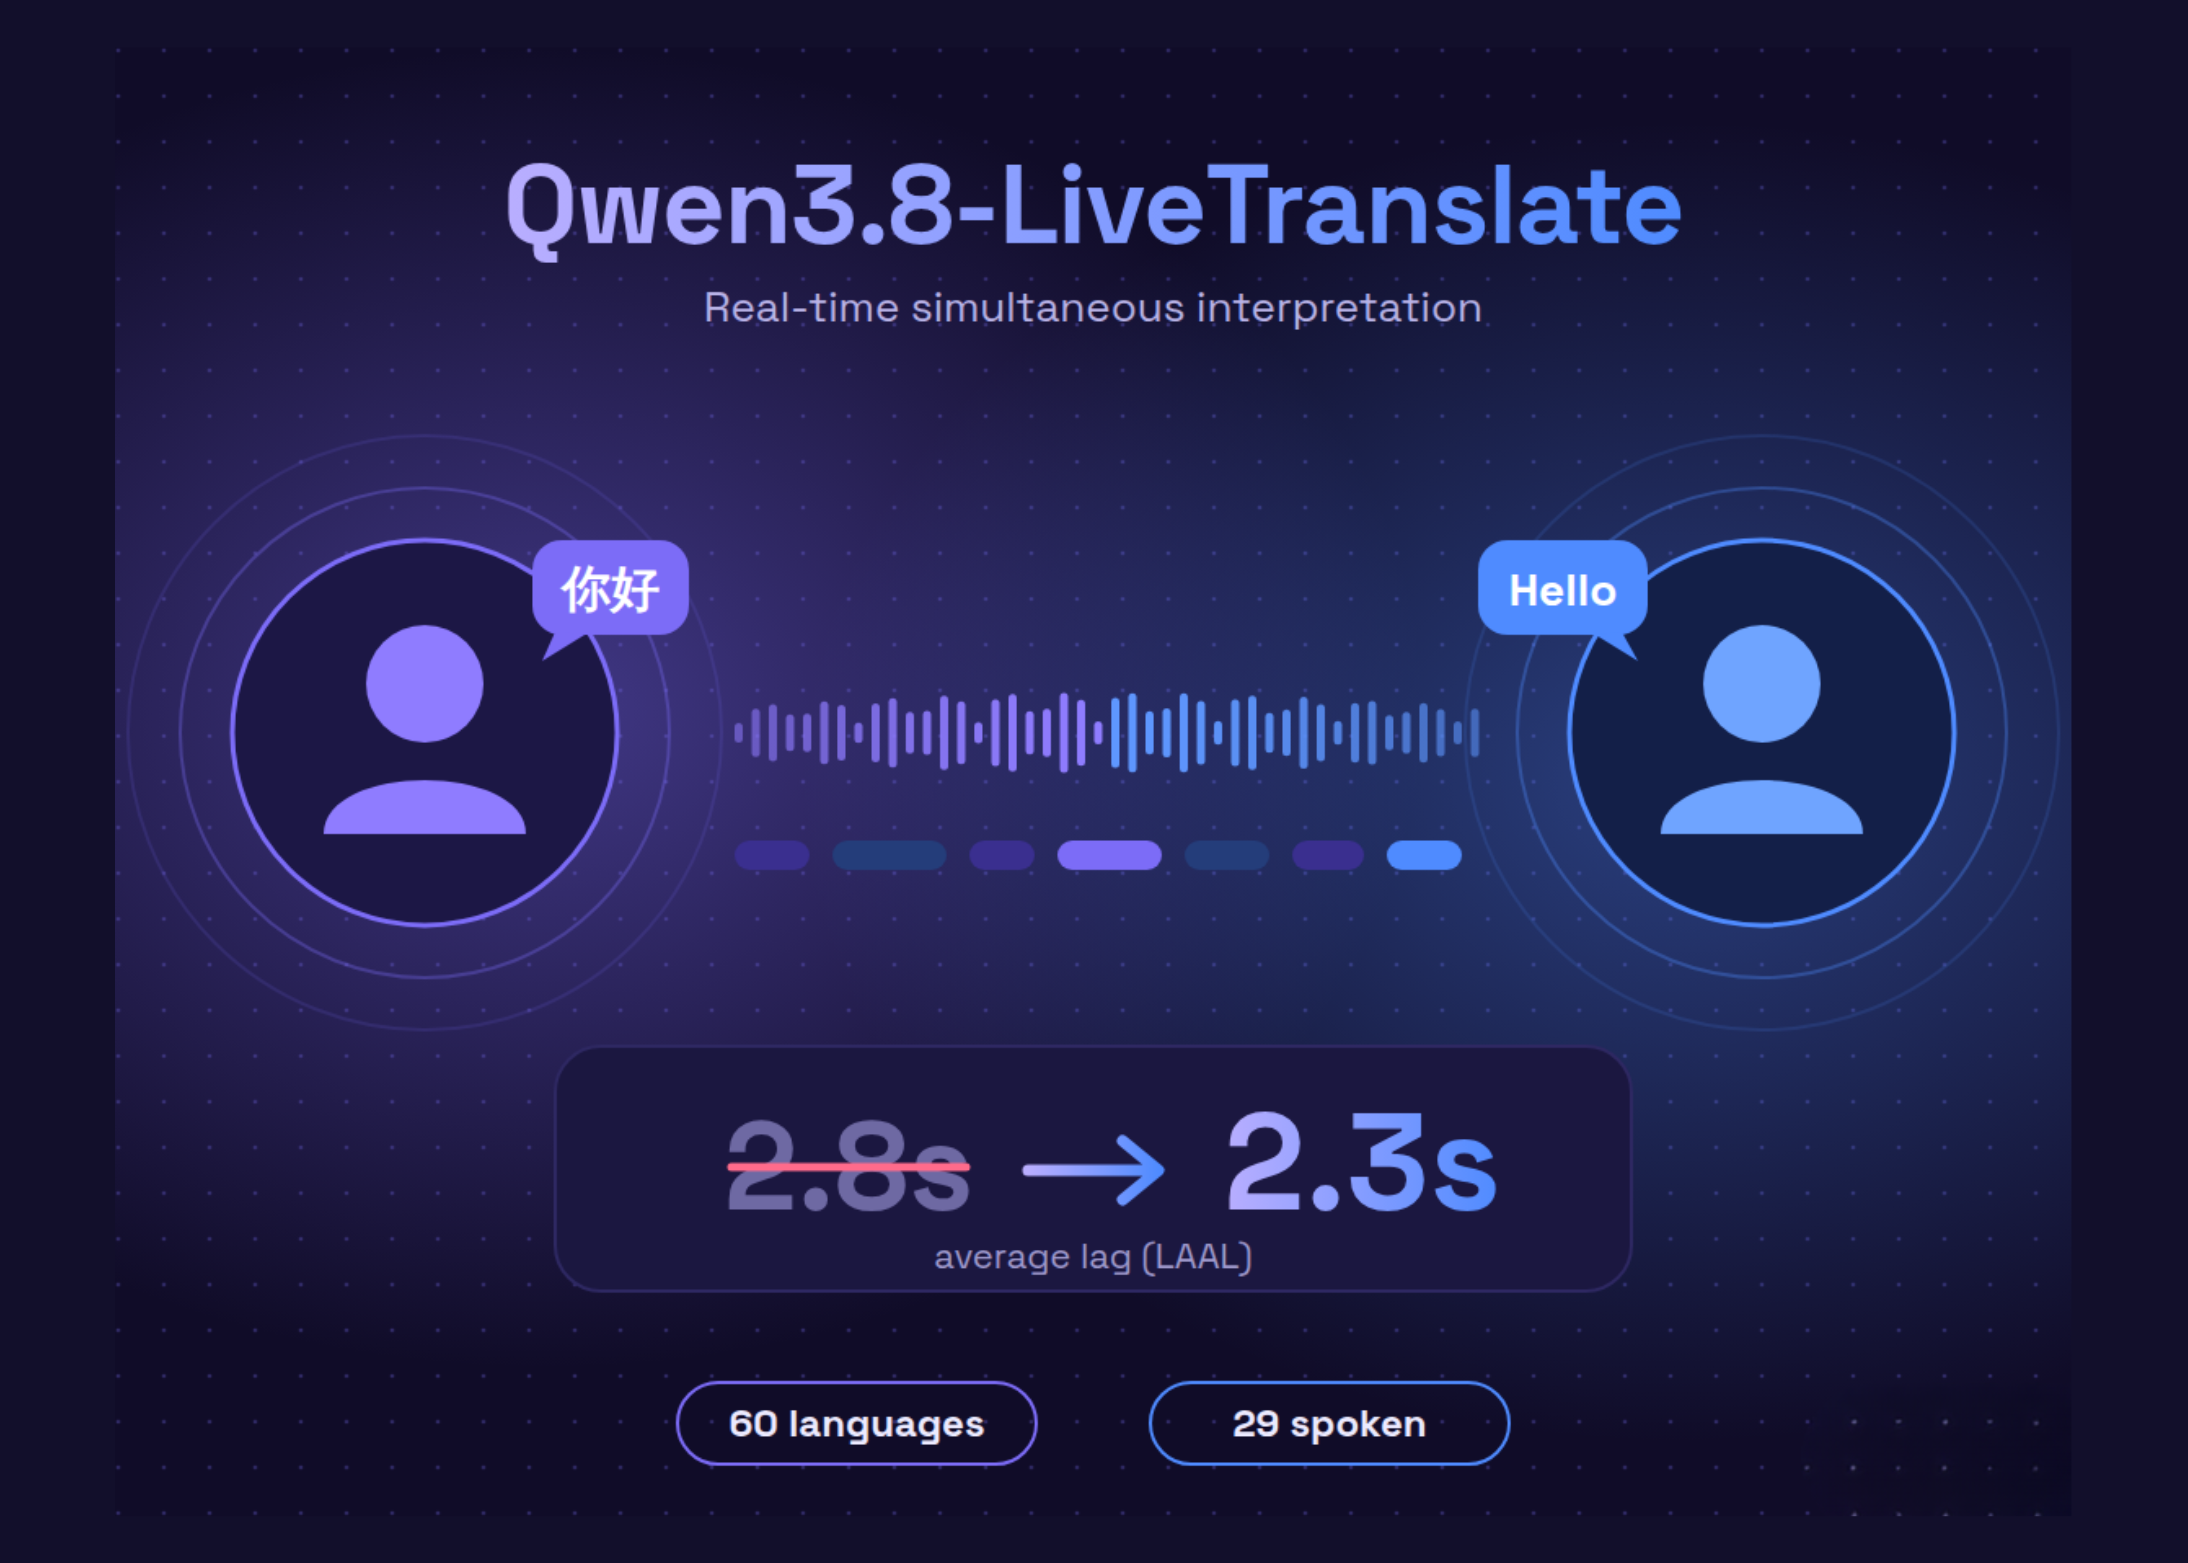
Qwen has released Qwen3.8-LiveTranslate , its next-generation real-time simultaneous interpretation model. It listens to live speech, with optional video frames, and returns translated text and speech while the speaker is still talking. The core change is a new Interleave architecture. Qwen reports gains in faithfulness, fluency, and conciseness, with average lagging (LAAL) dropping from 2.8 seconds to 2.3 seconds. The release also adds real-time speaker diarization, synchronized bilingual display, and long-context disambiguation. Deployable? Yes, as a hosted API. It is live on Alibaba Cloud Model Studio and QwenCloud as qwen3.8-livetranslate-flash-realtime over WebSocket. What Changed Under the Hood Simultaneous interpretation is a tradeoff. Waiting longer gives the model more context. Speaking sooner cuts delay for the listener. Qwen3.8-LiveTranslate rebuilds this loop with an Interleave architecture. The latency metric here is LAAL, or Length-Adaptive Average Lagging . It measures how far the translation trails the source speech on average. It also avoids rewarding systems that over-generate output. A drop from 2.8 seconds to 2.3 seconds is roughly an 18% cut in average lag. QwenCloud team describes the model as the real-time version of Qwen3.8-LiveTranslate-Flash. It builds on the Qwen-Omni stack, large-scale multimodal data, cross-language and cross-modal alignment, and visual enhancement. The Flash model also supports offline audio and video translation. Three New Capabilities Real-time speaker diarization : The model distinguishes speakers in multi-party speech. It a
Source: MarkTechPost